Practical AI
Measure an AI pilot without invented savings percentages
Establish a baseline and observe completed tasks, errors and review work before claiming results.
URBNBEE editorial team · October 3, 2026 · 2 min
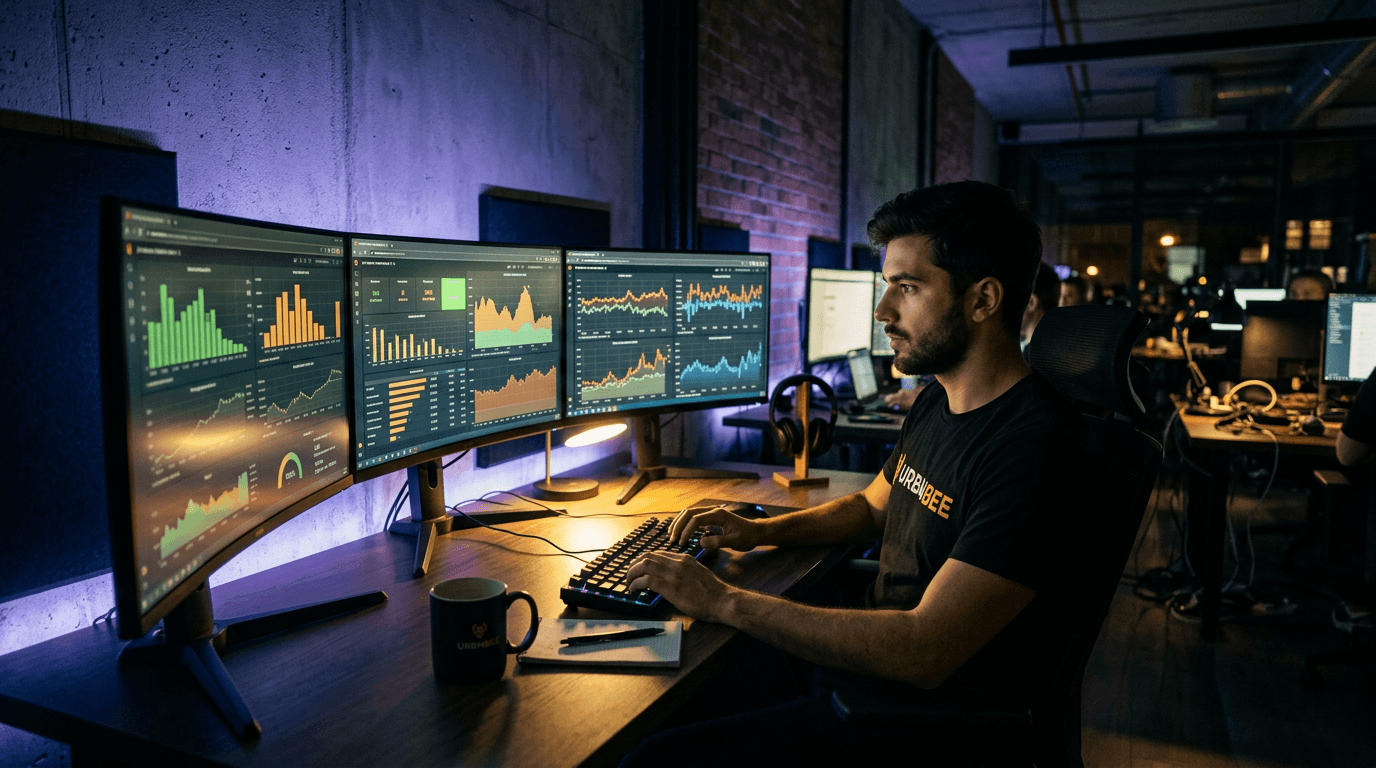
Observe before automating
For a comparable period, record inquiries, follow-up time and lost or corrected cases. You don't need perfect instrumentation, but consistent definitions matter. A sent reply is not a resolved order. Note seasonal changes or simultaneous promotions so you don't attribute unrelated changes to AI.
Count supervision costs too
A pilot may reduce repetitive replies while demanding intensive exception review. Count setup, knowledge maintenance and corrections. In a fictional example, less repetition of opening hours alongside more availability fixes is not a clear win. Evaluate informational inquiries, bookings, orders and quotes separately because effort and failure consequences differ.
Decide what to improve before scaling
Review conversations alongside recorded operations. Identify outdated knowledge, configuration issues, ambiguous intent or delayed human review. Correct an aspect and observe again. Evaluate BeeAgent against what your setup can resolve and how it supports handover. Don't publish savings or growth claims without explaining method, period and measurement limits.
Put it into practice
- Define handled requests and completed operations.
- Record a baseline using consistent criteria.
- Include setup, supervision and correction time.
- Segment by intent and compare reasonably similar periods.
- Document limits before communicating numerical results.
The takeaway
Honest measurement can reveal a modest, valuable improvement. Reproducible evidence supports decisions better than a spectacular number nobody can explain. Keep examples of successful requests and corrections without unnecessary personal data. Review them with colleagues to distinguish repeatable improvements from isolated good outcomes.
Editorial guidance, not a results promise. Capabilities depend on enabled tools and configuration; business examples are fictional.
Explore with fictional data →